Building a Production RAG Pipeline with Next.js
A practical walkthrough of building retrieval-augmented generation into a Next.js app — chunking, embeddings, vector storage, and retrieval that holds up past the demo stage.
Most RAG tutorials stop at the point where a demo works — ask a question, get a relevant chunk back, generate an answer. That's the easy 80%. The remaining 20%, which is most of what separates a demo from something you'd actually ship, is handling stale data, irrelevant retrieval, per-user access, and what happens when nothing relevant exists at all. This walkthrough covers the full pipeline with that gap in mind, in the context of a Next.js application.
If you're still deciding whether RAG is even the right approach for your use case, RAG vs fine-tuning vs long context is worth reading first — this guide assumes you've already landed on retrieval.
The Four Stages of a RAG Pipeline
Every RAG system, regardless of framework, does the same four things:
- Chunking — splitting source documents into smaller pieces
- Embedding — converting each chunk into a vector representation
- Storage and retrieval — storing those vectors and searching them at query time
- Generation — inserting retrieved chunks into a prompt and generating a response
Most quality problems in a live RAG system trace back to the first two stages, not the model itself — which is why it's worth spending real attention there instead of treating chunking as a quick preprocessing step.
Chunking: Getting the Split Right
Chunk size directly trades off two failure modes. Chunks that are too large dilute relevance — a single chunk might contain the answer buried among a lot of irrelevant surrounding text, weakening how well it matches a specific query. Chunks that are too small lose context — the answer might get split across two chunks, and retrieval might only surface one of them.
A practical starting point is a few hundred tokens per chunk with meaningful overlap between consecutive chunks, so information near a chunk boundary doesn't get orphaned. From there, the right size is something you tune against your actual content and query patterns, not a fixed number you set once and forget.
Structure matters too — splitting along natural boundaries (headings, paragraphs, list items) generally produces better chunks than splitting purely by token count, since it keeps semantically related content together.
Embeddings and Metadata
Each chunk gets converted into a vector via an embedding model, which is what enables similarity search later. This part is usually the least error-prone stage — the real leverage is in what you store alongside the vector.
Store metadata with every chunk: the source document, section or heading, last-updated date, and anything relevant to access control (which users or roles can see this content). This is far easier to build in from the start than to retrofit — adding proper citations or per-user filtering after your vector store already has thousands of chunks with no metadata means re-processing everything.
Storage and Retrieval
For a Next.js application already using Postgres — for example with Supabase, covered in our Next.js and Supabase auth guide — the pgvector extension lets you store embeddings directly alongside your existing relational data, avoiding a separate piece of infrastructure to run and secure. This is a reasonable default for most applications; dedicated vector databases become more attractive at very large scale or when you need retrieval features pgvector doesn't support well.
A basic similarity search alone often isn't enough once real usage starts. Two additions that matter in practice:
- Metadata filtering — narrowing the search to the right document set, user, or category before (or alongside) the similarity search, so you're not relying on vector similarity alone to exclude irrelevant content
- Re-ranking — retrieving a broader set of candidates with a fast initial search, then re-scoring the top results with a more precise (and more expensive) method before deciding what actually makes it into the prompt
Neither is necessary for a small proof of concept, but both tend to become necessary once a knowledge base grows past a modest size or query patterns get varied.
Generation: Assembling the Final Prompt
Once you have the right chunks, assembling the prompt is comparatively simple — insert the retrieved content, clearly separated from the user's question, along with instructions on how to use it (answer only from the provided context, cite sources, say "I don't know" if the context doesn't cover the question). That last instruction matters more than it sounds — a model handed irrelevant context will often still try to answer from it rather than admitting the retrieval came up empty.
What Actually Breaks in Production
The gap between a working demo and a production system is almost entirely about edge cases the happy path doesn't hit:
- Retrieval returns nothing relevant. The system needs a defined behavior here — telling the user rather than generating a plausible-sounding answer from irrelevant chunks.
- Content goes stale. Documents change; your pipeline needs a re-indexing strategy (scheduled, event-triggered, or on-demand) rather than a one-time ingestion script.
- Per-user or per-role access control. If different users should see different content, this has to be enforced at the retrieval/metadata-filtering step, not just in the UI — otherwise a clever prompt could surface content a user shouldn't see.
- Long-running conversations need memory beyond a single retrieval call. If your RAG system also needs to remember earlier turns in a conversation, that's a related but distinct problem — see AI agent memory systems for how that's typically handled.
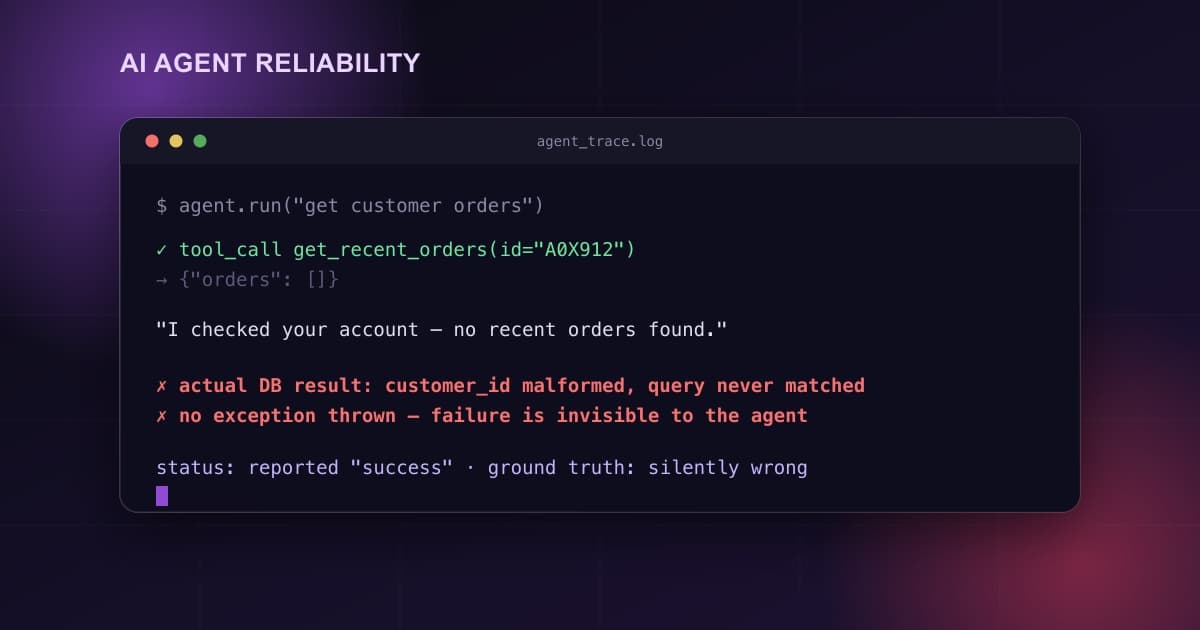
- You can't tell why a bad answer happened. Once this is live, observability and tracing for what was actually retrieved and generated becomes essential for debugging, not optional.
Key Takeaways
A production RAG pipeline is the same four stages as a demo — chunk, embed, store/retrieve, generate — but the real engineering work is in getting chunking and metadata right up front, adding retrieval filtering and re-ranking as the knowledge base grows, and explicitly handling the cases a happy-path demo skips: no relevant results, stale content, and access control. Getting the foundation right (chunking strategy and metadata) is far cheaper than retrofitting it after a knowledge base has already grown large.
If you're building a RAG feature into a product and want help getting the architecture right from the start, let's talk through your use case.