Decorative background gradient
Back to Blog
Ai Agent ArchitectureAgentic Loop DesignMulti Agent Systems

Modern AI Agent Architecture in 2026 — Patterns for Building Reliable Agents

The core architecture patterns behind reliable AI agents in 2026 — the agent loop, tool orchestration, memory layers, and when to use multi-agent.

Modern AI Agent Architecture in 2026 — Patterns for Building Reliable Agents

Most "AI agent architecture" discussions focus on which framework to use, but the frameworks all converge on the same handful of structural patterns underneath. Understanding those patterns directly is more durable than learning any one framework's API.

The Agent Loop: The Core Unit of Every Agent

Every agent, regardless of framework, is built around the same cycle: observe the current state, decide on the next action, execute it, and feed the result back in.

python

The max_iterations guardrail is not optional in production — without a hard stop, a model stuck in a bad decision pattern (retrying a failing action, or misreading its own tool output) will loop indefinitely and burn cost with no useful output.

Tool Orchestration: Fewer, Better-Scoped Tools Beat More Tools

A common mistake is exposing every available tool on every turn. Model tool-selection accuracy degrades measurably as the toolset grows, especially with tools that have overlapping purposes.

python

Scoping the toolset to what's actually relevant for the current step — rather than the full catalog at all times — is a structural fix, not a prompting fix, and it improves reliability more consistently than trying to word tool descriptions more carefully.

Layered Memory: Working, Session, and Persistent

A single context window can't hold an entire long-running task, so reliable agents separate memory into layers with different lifetimes.

python

Working context is what's directly relevant right now, session memory is a running summary that keeps a long task coherent without re-sending every prior turn verbatim, and persistent memory is what should survive across separate sessions entirely — user preferences, project facts, prior decisions.

Multi-Agent Systems: Only When Tasks Actually Decompose

A coordinator delegating to specialized subagents helps when subtasks are genuinely independent — but it adds real coordination overhead (aggregating results, handling partial failures, deduplicating work) that isn't worth paying for a task that's inherently sequential.

python

The right test for whether to decompose into multiple agents: do the subtasks need each other's intermediate results to proceed? If yes, a single agent with sequential steps is simpler and more reliable. If no — five independent file reviews, for example — parallel subagents reduce wall-clock time without adding coordination risk.

Guardrails: The Most-Skipped Architecture Layer

python

The most common production failure isn't an insufficiently capable model — it's an agent that compounds one wrong decision into several, because nothing in the architecture caps how many destructive actions it can take, or how many iterations it can loop through, before a human checks in.

Putting It Together

A reliable agent architecture in 2026 looks less like "pick a framework" and more like: a bounded agent loop with a hard iteration cap, a tool set scoped per step rather than exposed all at once, a layered memory system that keeps context bounded across long sessions, multi-agent decomposition reserved for genuinely parallel subtasks, and explicit guardrails around any action that's hard to undo.

Key Takeaways

The agent loop, tool orchestration, and layered memory are the structural patterns underneath every framework, scoping tools per step and capping iterations improve reliability more than better prompting does, multi-agent architectures pay off only for genuinely decomposable tasks, and most production agent failures trace back to unbounded context growth or missing guardrails rather than model capability.
Frequently Asked Questions

What is an "agent loop" in AI agent architecture?

The agent loop is the core control structure — the model observes the current state (the conversation and any tool results), decides on an action (respond, call a tool, or stop), executes it, and feeds the result back in as new context for the next iteration. Almost every production AI agent, regardless of framework, is built around this same observe-decide-act cycle.

When should I use a multi-agent architecture instead of a single agent?

When a task genuinely decomposes into independent subtasks that don't need to share full context — for example, reviewing five unrelated files for different concerns in parallel. For tasks that are inherently sequential or need full shared context throughout, a single agent with a well-designed tool set is usually more reliable and cheaper than coordinating multiple agents.

Why does giving an agent more tools sometimes make it less reliable?

Every additional tool in the available set increases the chance the model selects the wrong one, especially when several tools have overlapping or similarly-named capabilities. Scoping the available toolset to what's actually relevant for the current task step — rather than exposing every tool all the time — measurably improves tool selection accuracy.

What causes most production AI agent failures?

Unbounded context growth and missing guardrails on tool execution are more common root causes than the underlying model being insufficiently capable. An agent that never prunes stale context degrades in accuracy over long sessions, and an agent without limits on destructive actions (like file deletion or external API calls) can compound one bad decision into many.

Working on something similar? Take a look at my services and case studies, or book a free call to talk about your idea.

Related Articles

Silent Tool Failures in AI Agents — Why Your Agent Lies About Success
Ai Agent ReliabilityTool Call FailuresLlm Error Handling+1 more

Silent Tool Failures in AI Agents — Why Your Agent Lies About Success

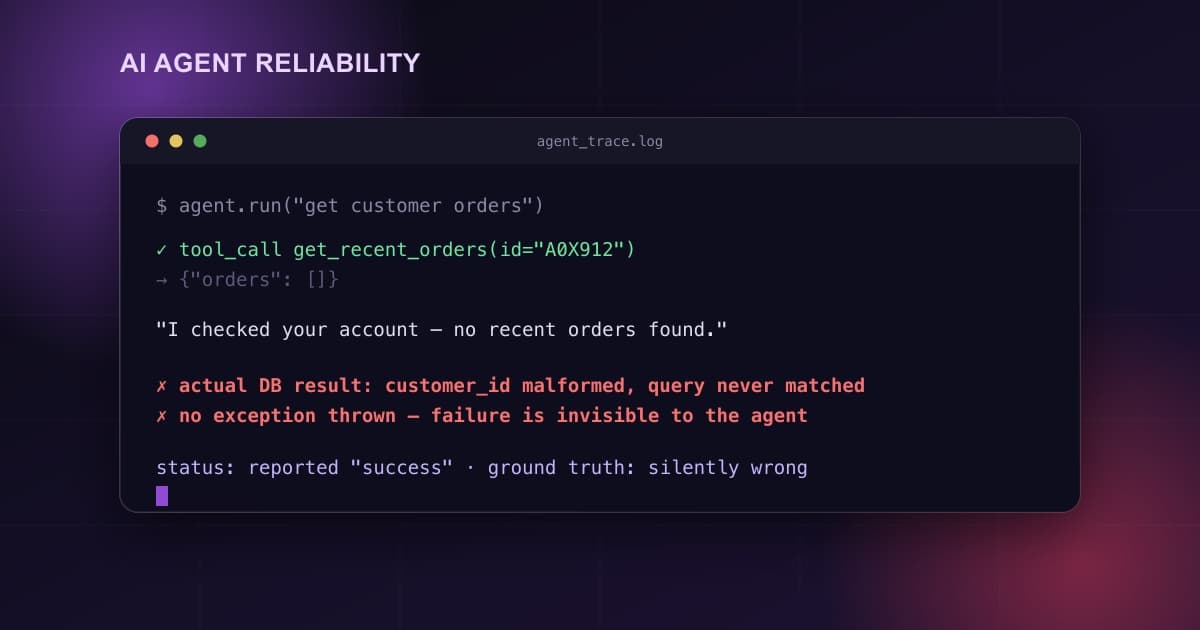
Most AI agent bugs never throw an error — the tool call "succeeds" with empty, truncated, or stale data and the agent confidently reports the task as done. Here's how to catch failures that don't look like failures.

September 22, 2026Read more →
AI Coding Agents Compared in 2026 — Claude Code vs Cursor vs GitHub Copilot
Claude Code Vs CursorAI Coding AgentsGithub Copilot

AI Coding Agents Compared in 2026 — Claude Code vs Cursor vs GitHub Copilot

Compare Claude Code, Cursor, and GitHub Copilot for real development work — agentic workflows, codebase understanding, pricing, and which fits your team.

September 18, 2026Read more →
Best Authentication Libraries for Next.js in 2026 — Clerk vs Auth.js vs Better Auth
Nextjs AuthenticationClerk Vs NextauthBetter Auth

Best Authentication Libraries for Next.js in 2026 — Clerk vs Auth.js vs Better Auth

Compare Clerk, Auth.js (NextAuth), and Better Auth for Next.js — setup effort, hosted UI, pricing, and which fits your app.

September 18, 2026Read more →
Best Error Monitoring & Analytics Tools for Next.js in 2026 — Sentry vs PostHog vs Vercel Analytics
Nextjs Error MonitoringSentry Vs PosthogWeb Analytics

Best Error Monitoring & Analytics Tools for Next.js in 2026 — Sentry vs PostHog vs Vercel Analytics

Compare Sentry, PostHog, and Vercel Analytics for a Next.js app — error tracking, product analytics, session replay, and pricing.

September 18, 2026Read more →
How to Add AI Features to an Existing Web App (Without a Rebuild)
Add AI To Existing AppAI SaaS FeaturesOpenAI API Integration

How to Add AI Features to an Existing Web App (Without a Rebuild)

A practical guide to adding real AI features, like matching, extraction, and automation, to a web app or SaaS product you already have, without rebuilding it from scratch.

September 16, 2026Read more →
AI Agent Observability and Tracing in Production
Ai Agent ObservabilityLlm TracingAgent Monitoring+2 more

AI Agent Observability and Tracing in Production

Why logging inputs and outputs isn't enough for AI agents in production — and how trace-level observability catches failures evals and logs miss.

September 14, 2026Read more →

Trending Topics