Decorative background gradient
Back to Blog
Model Context ProtocolMcp Server DesignAi Agent Tooling

Best Practices for MCP (Model Context Protocol) Server Design

Design a well-behaved MCP server — tool granularity, resource vs tool choice, error handling, and avoiding context bloat for the connecting agent.

Best Practices for MCP (Model Context Protocol) Server Design

MCP standardizes the wire protocol between an agent and an external tool or data source, but the protocol itself doesn't guarantee good tool design — the same principles that make any tool reliable for an LLM to use still apply, with a few MCP-specific wrinkles.

Step 1: Choose Resources vs Tools Based on Side Effects

MCP distinguishes resources (read-only data an agent pulls into context) from tools (actions an agent invokes, potentially with side effects). Picking the wrong primitive forces an unnecessary round trip.

python

Modeling read_file as a tool instead of a resource would still work mechanically, but it forces the agent through an unnecessary function-call-and-interpret step for something that's conceptually just "load this into context."

Step 2: Keep the Tool Set Small and Non-Overlapping

python

An MCP server with a dozen overlapping tools causes the same wrong-tool-selection problems as any oversized toolset — the protocol doesn't change the underlying model behavior that makes tool granularity matter.

Step 3: Bound Result Sizes by Default

python

Returning an unbounded result dumps everything into the connecting agent's context in one call, regardless of whether the agent needed all of it. A default limit with an explicit signal that results were truncated lets the agent decide whether to ask for more, rather than force-feeding a large payload every time.

Step 4: Return Structured, Actionable Errors

python

Because an MCP server may be maintained separately from the agent calling it, the error message is often the only channel through which the agent learns what a valid retry looks like — there's no shared codebase to fall back on for context.

Step 5: Version Tools Explicitly When Server Clients Are Unknown

python

An in-process tool built for one agent can change freely since only that agent depends on it. An MCP server may be connected to by multiple unrelated clients maintained by different teams, so a breaking schema change can silently fail clients the server's maintainer has no visibility into — explicit versioning and a deprecation window matter more here than for internal, single-agent tools.

Step 6: Document Tool Descriptions as Carefully as an API Contract

python

Since an MCP server's tool descriptions are the primary interface an unfamiliar agent uses to decide when and how to call it, they deserve the same care as a public API's documentation — including explicit guidance on when a different tool is the better choice.

Key Takeaways

MCP standardizes the transport between an agent and an external tool, but tool granularity, bounded results, and actionable errors still determine whether the connecting agent uses a server correctly — resources and tools should be chosen based on whether an operation is a pure data read or an action with side effects, and because MCP servers are often shared across unrelated clients, versioning and deprecation deserve more care than they would for a single agent's internal tools.
Frequently Asked Questions

When should an MCP server expose something as a resource instead of a tool?

Use a resource when the agent just needs to read data into context — a file, a document, a database record — with no side effect and no parameters beyond identifying which resource to fetch. Use a tool when the agent needs to invoke an action, pass parameters that shape the operation, or trigger a side effect. Modeling a plain data fetch as a tool forces an unnecessary function-call-and-interpret round trip for something that's really just a context read.

How many tools should one MCP server expose?

As few as the server's actual capability set requires, each with a clearly distinct purpose. The same tool-selection accuracy problems that affect any large toolset apply to MCP servers — an agent connected to a server with a dozen overlapping tools will more frequently pick the wrong one than an agent connected to a server with a handful of clearly differentiated ones.

Should an MCP tool return the full result of a large query?

No — return a bounded, paginated, or summarized result by default, with an explicit way for the agent to request more if needed. An MCP tool that dumps an entire large dataset into a single response bloats the connecting agent's context exactly like an oversized tool result would in any other tool-calling architecture, regardless of the protocol used to deliver it.

Why does versioning matter more for MCP servers than for tools built into a single agent?

An in-process tool only affects the one agent it's built for, so changing its behavior is a self-contained decision. An MCP server can be connected to by multiple unrelated agent clients maintained by different teams, so a breaking change to a tool's schema or behavior can silently break clients the server's maintainer doesn't control — which is why explicit versioning and deprecation notices matter more here than for a single agent's internal tools.
Working on something similar? Take a look at my services and case studies, or book a free call to talk about your idea.

Related Articles

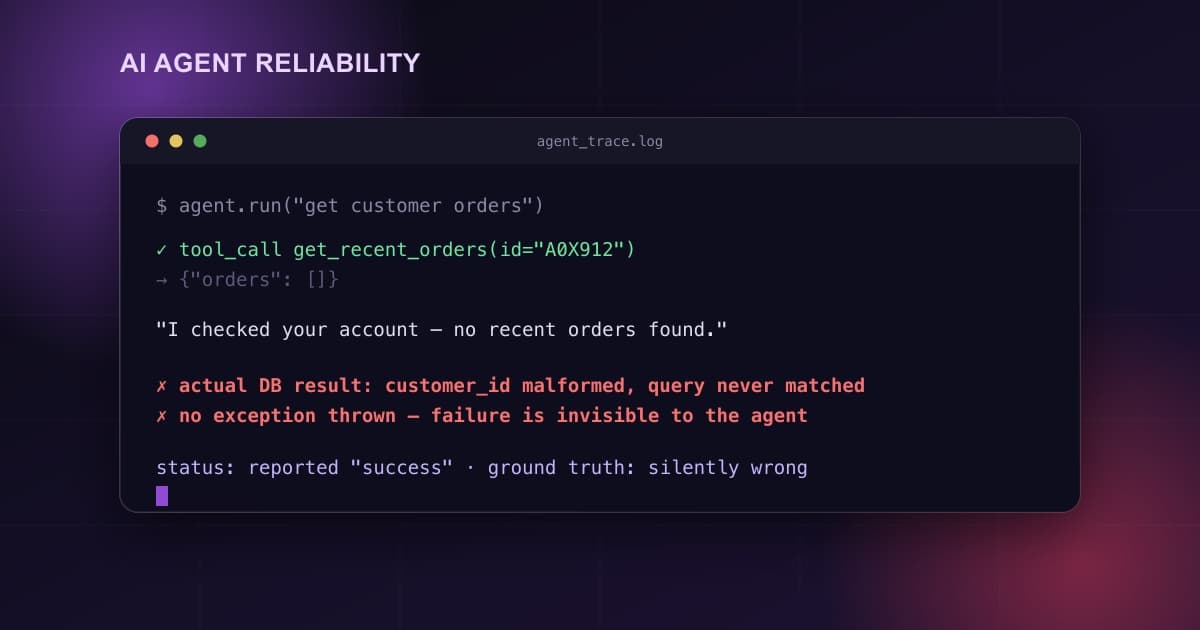
Silent Tool Failures in AI Agents — Why Your Agent Lies About Success
Ai Agent ReliabilityTool Call FailuresLlm Error Handling+1 more

Silent Tool Failures in AI Agents — Why Your Agent Lies About Success

Most AI agent bugs never throw an error — the tool call "succeeds" with empty, truncated, or stale data and the agent confidently reports the task as done. Here's how to catch failures that don't look like failures.

September 22, 2026Read more →
AI Coding Agents Compared in 2026 — Claude Code vs Cursor vs GitHub Copilot
Claude Code Vs CursorAI Coding AgentsGithub Copilot

AI Coding Agents Compared in 2026 — Claude Code vs Cursor vs GitHub Copilot

Compare Claude Code, Cursor, and GitHub Copilot for real development work — agentic workflows, codebase understanding, pricing, and which fits your team.

September 18, 2026Read more →
Best Authentication Libraries for Next.js in 2026 — Clerk vs Auth.js vs Better Auth
Nextjs AuthenticationClerk Vs NextauthBetter Auth

Best Authentication Libraries for Next.js in 2026 — Clerk vs Auth.js vs Better Auth

Compare Clerk, Auth.js (NextAuth), and Better Auth for Next.js — setup effort, hosted UI, pricing, and which fits your app.

September 18, 2026Read more →
Best Error Monitoring & Analytics Tools for Next.js in 2026 — Sentry vs PostHog vs Vercel Analytics
Nextjs Error MonitoringSentry Vs PosthogWeb Analytics

Best Error Monitoring & Analytics Tools for Next.js in 2026 — Sentry vs PostHog vs Vercel Analytics

Compare Sentry, PostHog, and Vercel Analytics for a Next.js app — error tracking, product analytics, session replay, and pricing.

September 18, 2026Read more →
How to Add AI Features to an Existing Web App (Without a Rebuild)
Add AI To Existing AppAI SaaS FeaturesOpenAI API Integration

How to Add AI Features to an Existing Web App (Without a Rebuild)

A practical guide to adding real AI features, like matching, extraction, and automation, to a web app or SaaS product you already have, without rebuilding it from scratch.

September 16, 2026Read more →
AI Agent Observability and Tracing in Production
Ai Agent ObservabilityLlm TracingAgent Monitoring+2 more

AI Agent Observability and Tracing in Production

Why logging inputs and outputs isn't enough for AI agents in production — and how trace-level observability catches failures evals and logs miss.

September 14, 2026Read more →

Trending Topics